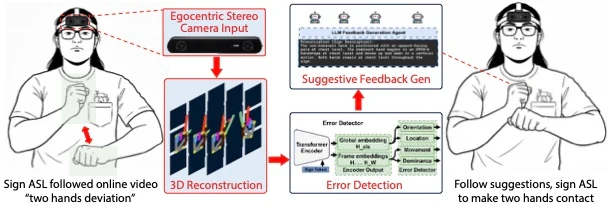
EgoSSA: Egocentric Stereo Structure-Aware 3D Hand Reconstruction for American Sign Language Gesture Modeling
A geometry- and structure-aware stereo framework for stable 3D reconstruction of fast, frequently occluded ASL hand motion from a first-person view.
The idea
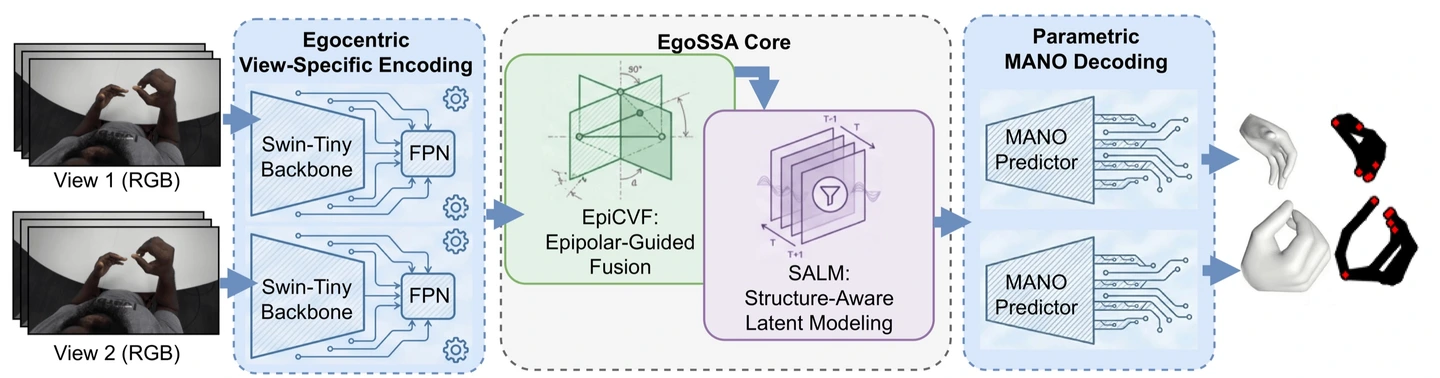
Fast two-handed signing is unusually difficult to reconstruct: hands occlude one another, motion blur removes detail, and monocular video loses depth. EgoSSA uses a synchronized stereo view and explicit structural priors to recover stable 3D hand motion.
The technical core
Two Swin-Tiny encoders and feature pyramids preserve view-specific detail. Epipolar-Guided Cross-View Fusion uses geometric constraints with deformable attention, while Structure-Aware Latent Modeling captures anatomical and temporal consistency before MANO-based decoding.
Why it matters
Accurate egocentric reconstruction provides a geometric foundation for privacy-preserving ASL recognition, translation, and tutoring systems. The accompanying EgoStereoASL-10 dataset also creates a new benchmark for realistic first-person signing.